The Essay and the Multiple-Choice Exam: How Jev Works vs. a Normal LLM
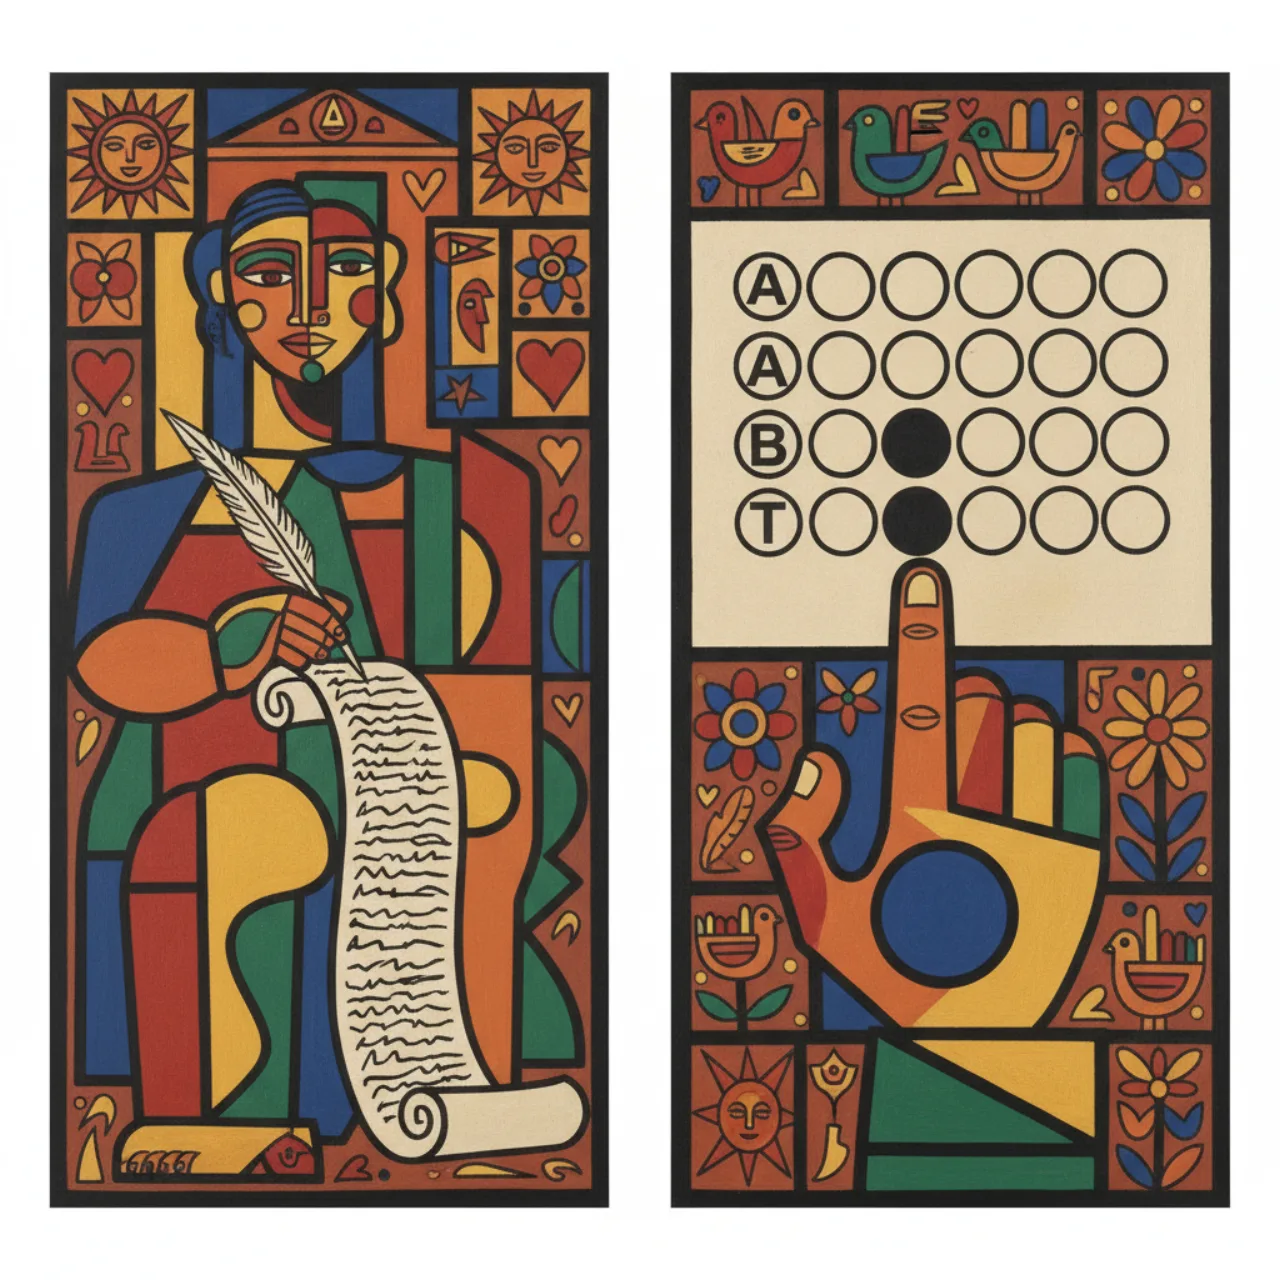
I've been writing about Jev and the new class of small "System One" decision models for a couple of weeks now. The topic came up again on Merge Conflict episode 534 ("Why Developers Are Obsessed with Budget LLMs"), and it pushed me to find the simplest possible way to explain how a model like Jev actually differs from the GPT-shaped LLM you already use. Here's the analogy I landed on, built from how the two things work under the hood.
A normal LLM answers every question like an essay. Jev answers like a multiple-choice exam.
That's the whole thing. Everything else — the speed, the "0% malformed," the calibrated confidence — falls out of that one difference.
The essay-writer
Ask a normal LLM anything and it does exactly one thing: it predicts the next token, appends it, and repeats. It is an autoregressive model — each word it writes is conditioned on every word it has written so far. That's true whether you ask it to write a poem or to "return the answer as JSON." To give you {"team": "billing"}, it literally writes that out character by character: {, then ", then t, e, a, m… sampling from a probability distribution at every single step.
This is a student answering an essay question. They start writing, and each sentence follows from the last. It's powerful — an essay can say anything — but for a decision, it has three costs:
- It's sequential. An N-token answer is N forward passes through the model, one after another. Writing "billing" is cheap; writing a paragraph of reasoning first is not. You pay per word.
- It can wander off the page. Nothing forces the essay to end on a valid answer. It can misspell your enum, add a trailing comma, wrap the JSON in an apology, or invent a category you never offered. Then you have to grade it — parse it, validate it, and hope.
- Its confidence is about the next word, not your question. The model knows the probability of the next token. It does not, by default, hand you "I'm 82% sure the answer is billing." You asked a question with three possible answers; it gave you a probability distribution over its entire vocabulary, one token at a time.
Most "ask the LLM for JSON and pray" pain is this: you handed a bounded decision to an essay-writer.
The multiple-choice test-taker
Now picture the same student with a Scantron sheet. The question is printed, the options are printed — A, B, C — and the job is to read them and bubble in the best one. They can't misspell the answer. They can't invent a fourth option. They can't write three paragraphs. The answer space is the set of bubbles.
That is what Jev does. You hand it the context and the fixed set of options, and instead of generating an answer, it scores each option. Concretely: it reads the context once, then for each candidate option it computes how likely that option's text is given the context — the log-probability of "billing," of "technical," of "sales" — and runs a softmax over those scores to get a probability for each. Then it bubbles the highest one. No token-by-token generation of the answer. The output is one of your options, always, plus a real distribution over all of them.
Look at what each of the essay-writer's three costs turns into:
- It's essentially one pass, not N. Prefill the context, score the options together, done. This is why a model like the open-source open-jev scores eight options in about 0.17 seconds — there's no paragraph to write.
- It cannot produce malformed output. There's nothing to malform. The value is a bubble, not free text. That's the "0% structured-output error rate" claim, and it's not a heroic feat of prompting — it's a property of scoring a closed set instead of generating an open one.
- You get a calibrated probability over the actual options. Because it scored your options against each other, the number it returns ("billing, 0.82") is about your question. A well-tuned decision model makes that number track reality, which is what lets you set a threshold and escalate when it's unsure.
Here's the twist: the multiple-choice method is the old one
This isn't a new invention. It's how the machine-learning field has always scored multiple-choice benchmarks. Open up any evaluation harness and the way it grades a question like HellaSwag or ARC is exactly this: it takes each answer choice, measures the model's log-likelihood of that choice given the prompt, and picks the highest. The headline accuracy number on those leaderboards, acc_norm, even divides each choice's log-likelihood by its length first — to stop the model from favouring shorter answers just because they have fewer tokens to be uncertain about.
If that length-normalization sounds familiar, it's the same knob open-jev exposes as norm: "mean" | "sum" | "pmi". The scoring trick Jev sells was sitting inside every benchmark script the whole time. What's genuinely new is a model purpose-built and tuned to be excellent at the bubbling — fast, cheap, and calibrated — and shipped as a product with an API instead of buried in an eval loop.
There's even a nice piece of evidence for why you'd want the real multiple-choice method over faking it. If you try to make an essay-writer do multiple choice by printing "answer A, B, or C" and reading its next letter, its score can swing wildly when you merely shuffle the options around — a known quirk called Multiple-Choice Symbol Binding. That's the essay-writer being flustered by a format it wasn't built for. Scoring the option text directly, the way Jev does, sidesteps the whole problem: it never has to bind an answer to a letter, it just weighs the answers themselves.
So which student do you want?
Not always the multiple-choice one. The essay-writer earns its keep on anything genuinely open-ended: writing code, drafting prose, working through a multi-step problem where the reasoning is the point. You can't bubble your way to a proof. That's the System 1 / System 2 split — the essay is your slow, deliberate thinker, and it's irreplaceable when the task is actually hard.
But an enormous share of what we shove through LLMs isn't hard. "Which team gets this ticket?" "Is this review positive?" "Pick a category." Those are multiple-choice questions, and we've been answering them with essays — paying for paragraphs, parsing the output, and getting no honest confidence — because for a few years the essay-writer was the only student in the room. Jev, Luna, and the other budget decision models are simply the test-taker showing back up.
The next time you find yourself writing a prompt that ends in "…and respond only with valid JSON, no other text," stop and notice what you're really doing: you're begging an essay-writer to behave like a Scantron. There's a model for that now.
Building bounded decisions in .NET? I keep every one of these engines behind a single IDecider interface at github.com/egarim/systemone-deciders — swap the essay-writer for the test-taker without your code noticing. And if you caught the Merge Conflict episode that sparked this, tell me whether Frank's analogy beat mine via the links on the about page.